

reasoning_content field. This field contains the
model’s internal reasoning, which would otherwise appear in <think></think>
tags within the content field. For some models, the reasoning content may
instead be included directly in the content field itself.
Prerequisites
We recommend using the Fireworks Python SDK to work with reasoning, as it supports Fireworks-specific parameters and response fields.Basic usage
Select a reasoning model from our serverless model library.Controlling reasoning effort
You can control the reasoning token length using either thereasoning_effort parameter or the Anthropic-compatible thinking parameter.
Coming from NVIDIA NIM or vLLM? Fields like chat_template_kwargs.enable_thinking are mapped onto reasoning_effort automatically. See NIM compatibility.
Using reasoning_effort
The reasoning_effort parameter accepts string values like "low", "medium", or "high":
Using thinking (Anthropic-compatible)
Alternatively, you can use the thinking parameter, which provides an Anthropic-compatible format for controlling reasoning behavior:
Streaming with reasoning content
When streaming, the reasoning content is available in each chunk’s delta:Interleaved thinking
When building multi-turn tool-calling agents with models that support interleaved thinking, you MUST include thereasoning_content from previous
assistant turns in subsequent requests. This enables the model to think between tool calls and after receiving tool results, allowing for more complex, step-by-step reasoning.
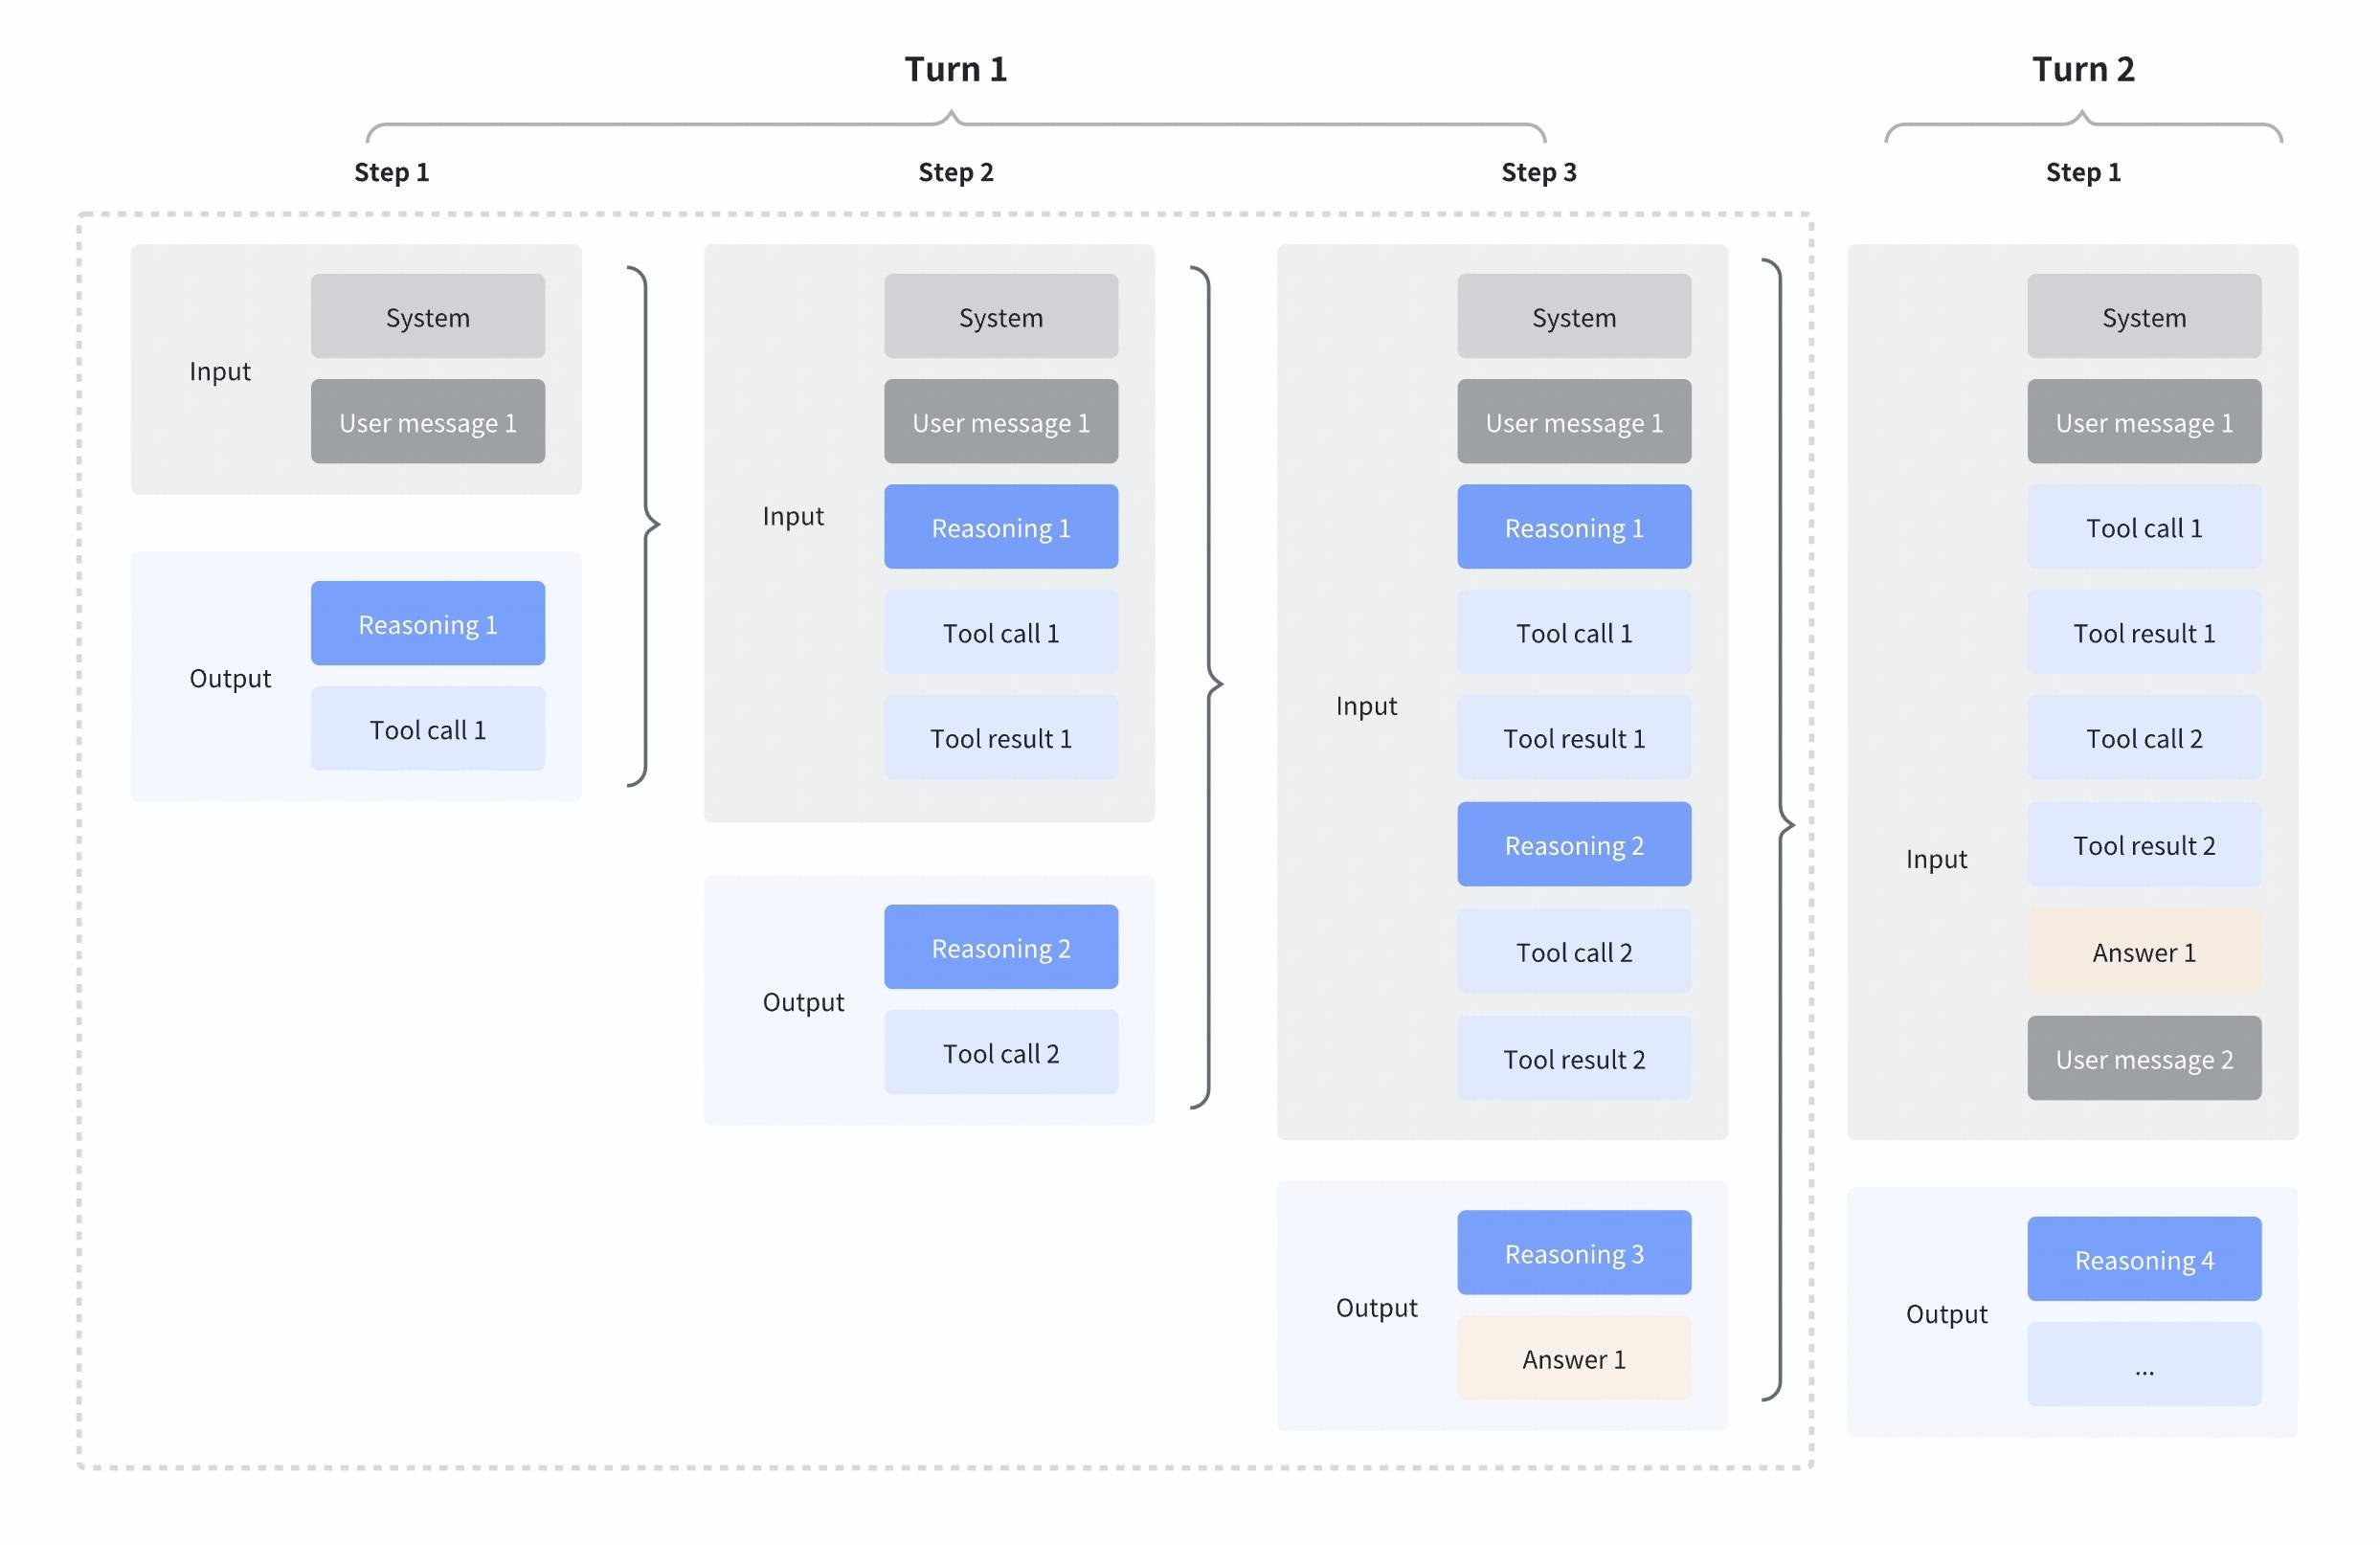
Interleaved thinking: the model reasons between tool calls within a single turn. Source: Z.AI
- Pass the
Messageobject directly (recommended) - The SDK message object already contains thereasoning_contentfield alongsidecontentandtool_calls - Manually include
reasoning_content- When constructing messages as dictionaries, explicitly add thereasoning_contentfield
Interleaved thinking is triggered when the last message in your API request
has
"role": "tool", enabling the model to use its previous reasoning process
when responding to the tool result. If a model does not support interleaved
thinking, it simply ignores the extra reasoning context so this pattern is
safe to use broadly.Trained models: whether historical
reasoning_content was visible during
training depends on the base model and the job’s thinking-history mode.
Interleaved removes thinking across user-turn boundaries while retaining the
assistant/tool trajectory within the current turn; Preserved retains thinking
across user turns. Datum unrolling is model-specific. For reliable results,
serve a trained model consistently with how it was trained; see
thinking history in training
for per-model behavior.- Pass Message object
- Manual dictionary
- Anthropic SDK
reasoning_content from the first turn is included in subsequent requests:
main.py
Preserved thinking
While interleaved thinking preserves reasoning within a single turn (across tool calls), preserved thinking extends this concept across multiple user turns. This allows the model to retain reasoning content from previous assistant turns in the conversation context, enabling more coherent multi-turn reasoning.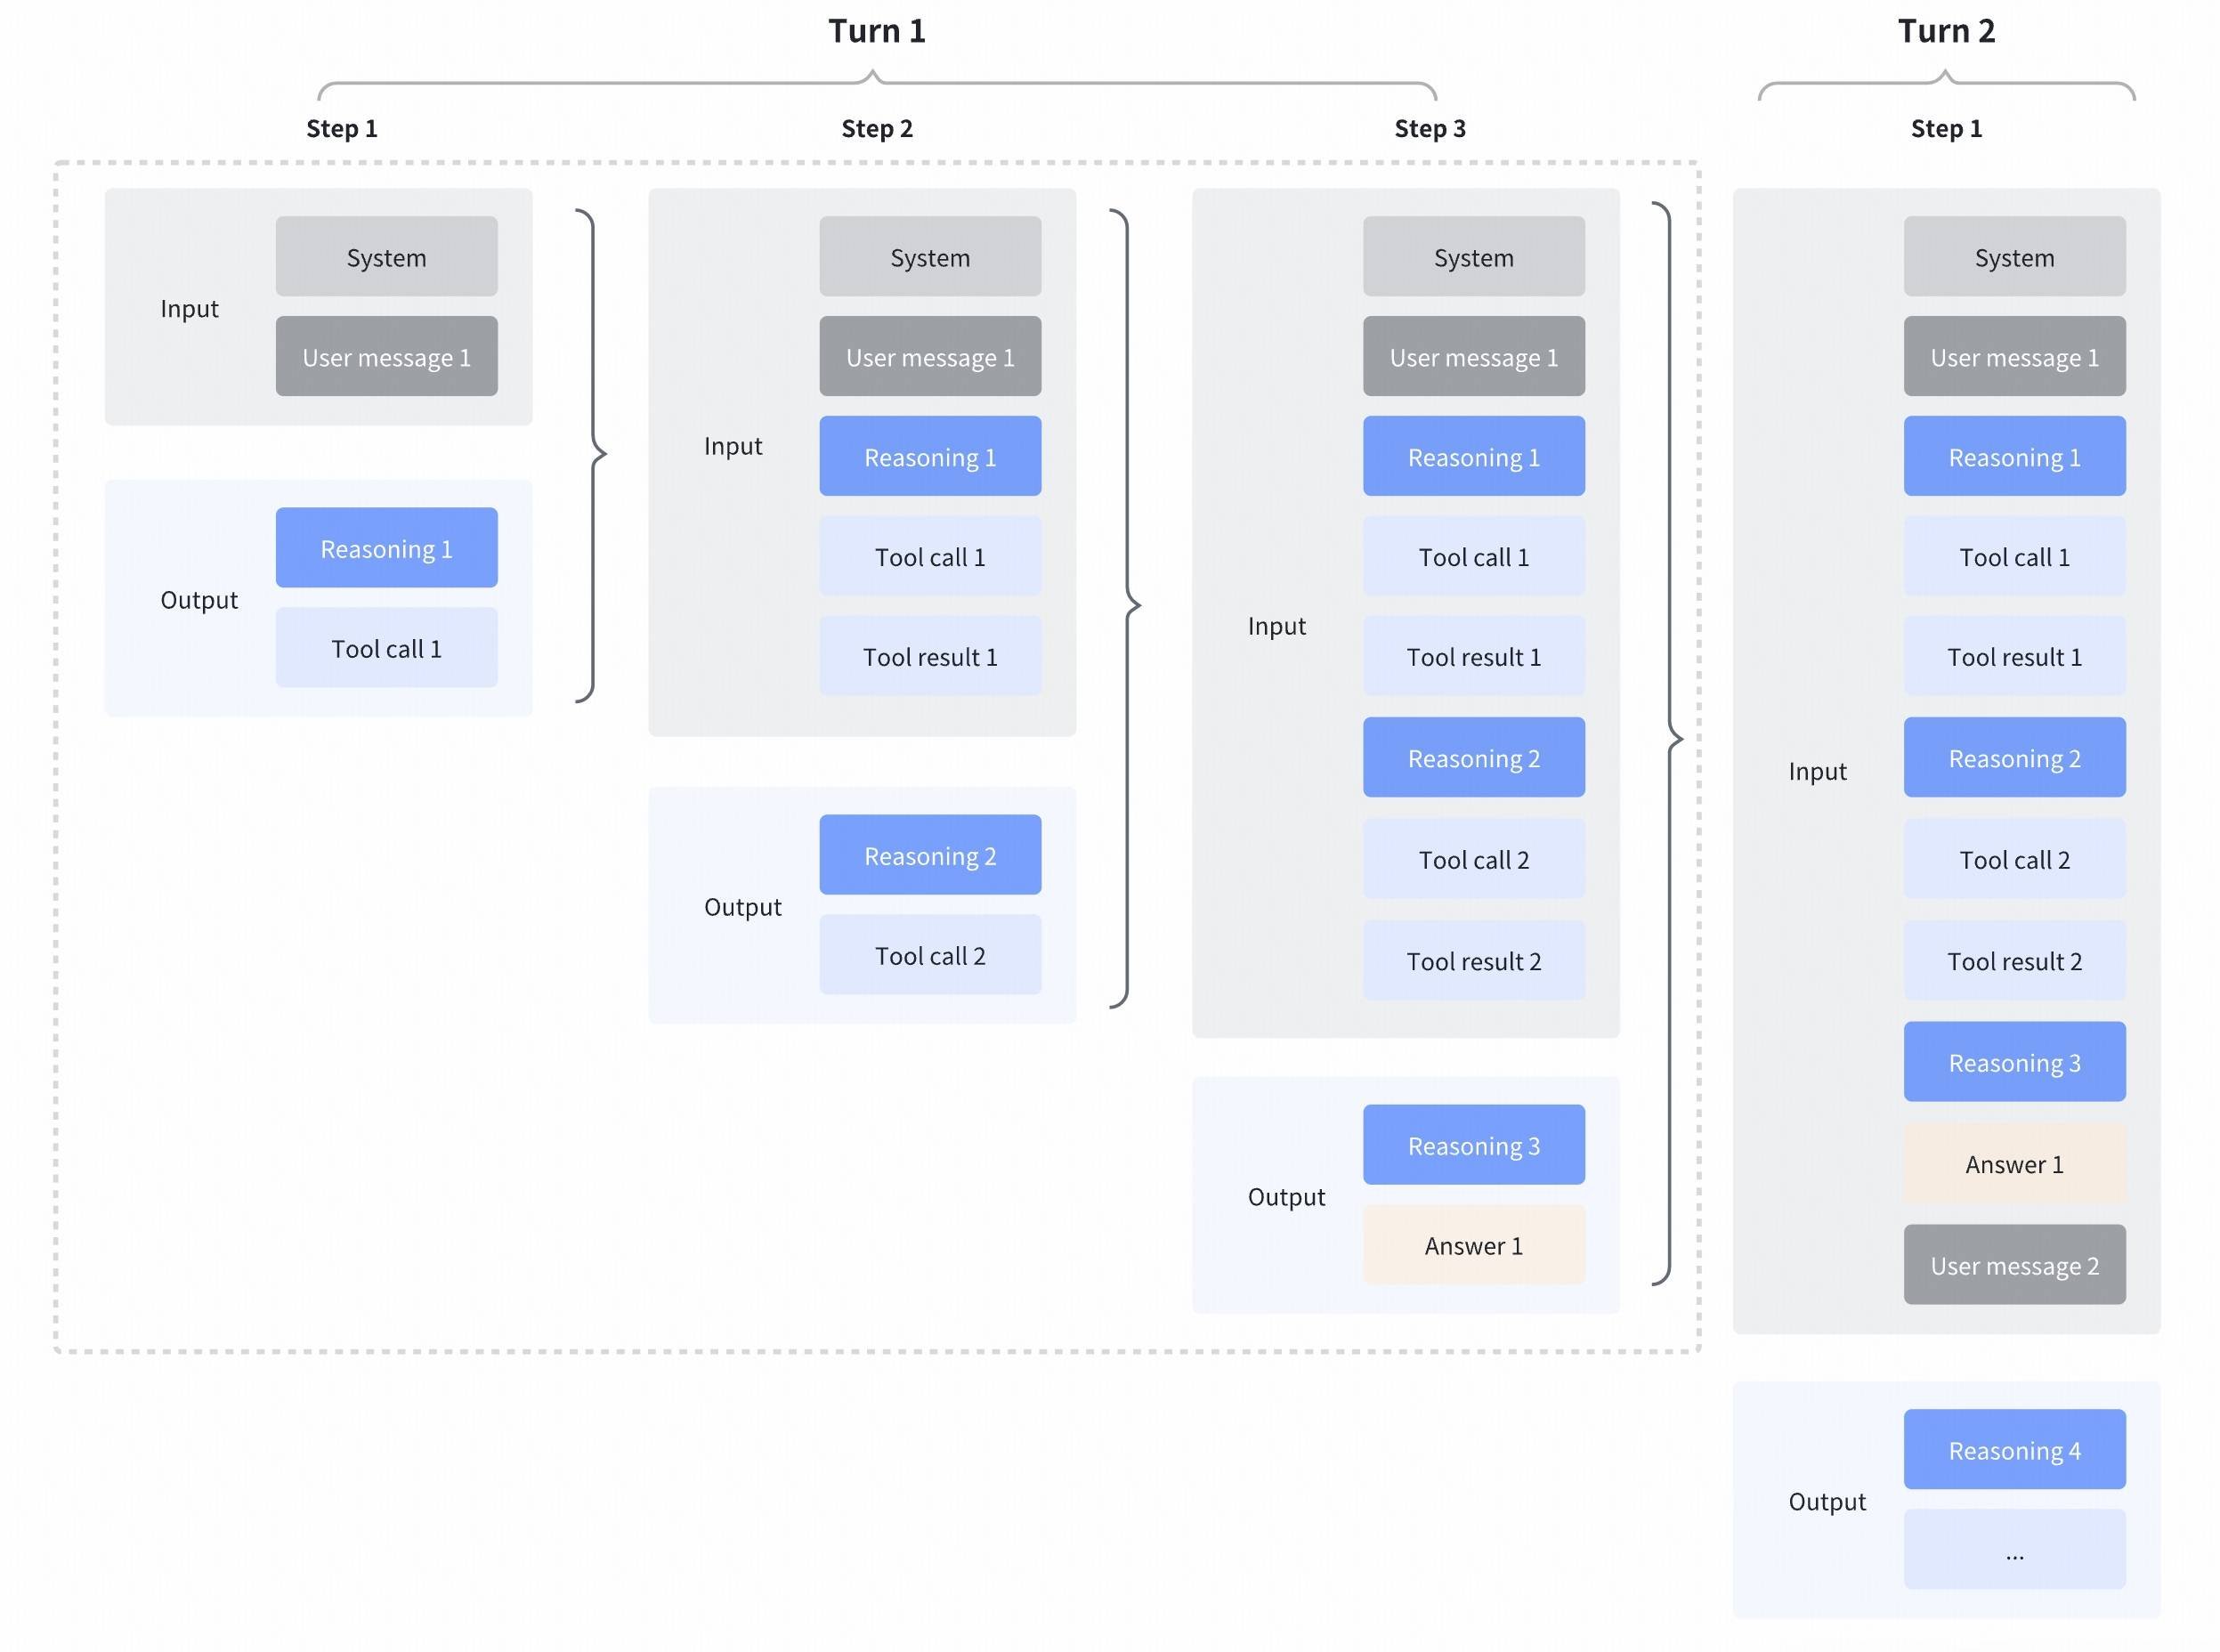
Preserved thinking: reasoning from previous turns is retained and passed to subsequent turns. Source: Z.AI
Controlling reasoning history
You can control how historical reasoning content is included in subsequent requests using thereasoning_history parameter:
reasoning_history parameter for all accepted values.
When
reasoning_history is set to "preserved", the model receives the full reasoning context from all previous turns. This is particularly useful for complex multi-turn conversations where maintaining reasoning continuity is important.reasoning_content as the mode requires and passes preserve_thinking to the model’s chat template: true for "preserved", false for "interleaved" and "disabled", and nothing when reasoning_history is unset, so the template’s own default applies. With preserve_thinking on, the official Qwen template adds an empty <think>\n\n</think>\n\n block to earlier assistant turns that have no reasoning_content:
In every mode, assistant turns after the last user message, such as an in-progress tool-calling loop, keep a
<think> block. With "disabled", that block is empty.
If you train with thinking history, use the same mode when you serve the model.
The following script demonstrates preserved thinking across multiple turns and validates that
reasoning_content from all previous turns is included in subsequent requests:
main.py
GLM-4.7 (output)